
Foreign Key: What It Is & Why Databases Need It
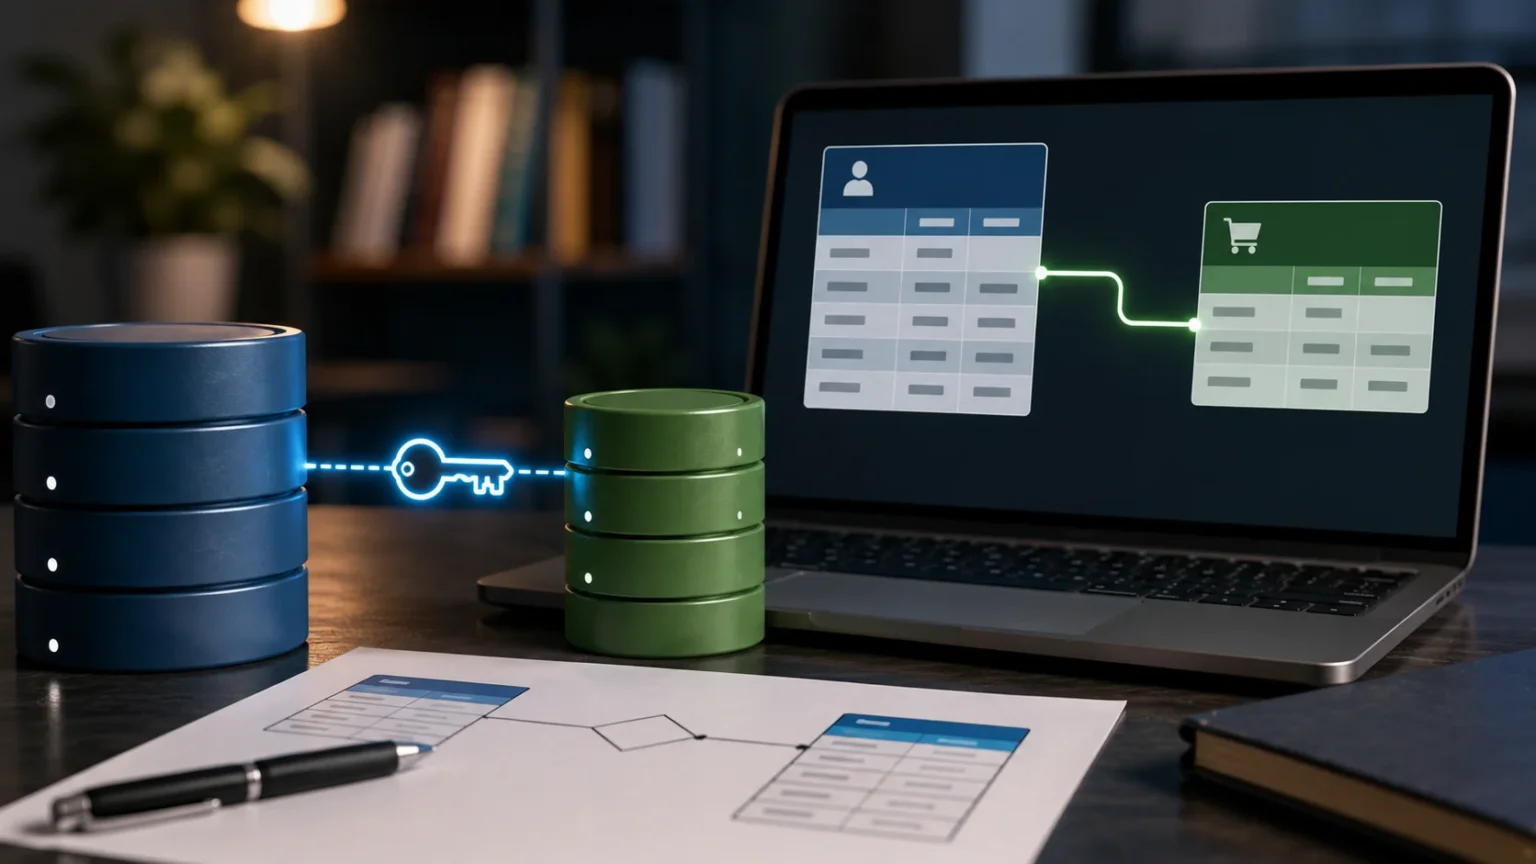
A foreign key is one of the most important concepts in relational databases because it helps connect data stored in different tables. Instead of repeating the same information across many places, databases can store related data separately and use foreign keys to create relationships between those records. For example, a customer table may store customer details while an orders table stores purchases. The orders table can include a customer ID that points back to the matching customer record. That customer ID becomes a foreign key when it references the primary key or another unique key in the customer table. This simple relationship makes database systems more organized, efficient, and reliable.
Foreign keys are especially useful because modern applications rarely keep all information in a single database table. Ecommerce platforms, banking systems, healthcare applications, social networks, inventory tools, and business software may contain hundreds or thousands of interconnected tables. Without clear relationships between those tables, data can quickly become inconsistent or difficult to manage. A foreign key allows the database to understand that one record depends on or belongs to another record. It can also prevent certain types of invalid data from being saved. This protection is part of what database professionals call referential integrity.
Consider an online store with separate tables for customers and orders. Each customer receives a unique customer ID, and each order contains the ID of the customer who placed it. Rather than copying the customer’s name, address, phone number, and other details into every order record, the database can reference the customer through that ID. If a customer places 20 orders, those 20 records can all point to the same customer record. This reduces unnecessary duplication while making updates easier. If the customer changes a profile detail, the business may only need to update the appropriate customer record instead of correcting information throughout many order rows.
Foreign keys also help developers express business relationships clearly in a database schema. A product can belong to a category, an employee can belong to a department, a comment can belong to a blog post, and an invoice can belong to a customer. Each of these relationships can often be represented through foreign key constraints. Databases can then enforce rules about whether referenced records exist and what should happen when those records change. Depending on the design, a deletion might be blocked, cascaded to related rows, or converted to a null reference. These options allow database behavior to match real application requirements more closely.
Understanding what a foreign key is and why databases need it is essential for anyone learning SQL, relational database design, backend development, data engineering, or application architecture. The concept appears frequently in systems using MySQL, PostgreSQL, SQL Server, Oracle Database, SQLite, and other relational database management systems. This guide explains foreign key relationships, primary keys, referential integrity, one-to-many and many-to-many relationships, SQL examples, cascading actions, common errors, and best practices. The goal is to make foreign keys understandable even if you are new to database terminology. Once the concept becomes clear, many other relational database ideas become much easier to understand.
What Is a Foreign Key in a Database?
A foreign key is a column, or sometimes a combination of columns, in one database table that references a key in another table or occasionally another record within the same table. The referenced key is usually a primary key, although some database systems allow a foreign key to reference another candidate or unique key. The table containing the foreign key is often called the child or referencing table. The table containing the referenced key is often called the parent or referenced table. This relationship helps the database understand how records are connected. It also allows the database engine to enforce rules that keep those connections valid.
Imagine a database with a customers table and an orders table. The customers table may contain a customer_id column that uniquely identifies every customer. The orders table may also contain a customer_id column to indicate which customer placed each order. In the customers table, customer_id can be the primary key. In the orders table, the same type of value can act as a foreign key referencing customers.customer_id. This setup creates a relationship between each order and an existing customer. The database can reject an order that references a customer ID that does not exist if the foreign key constraint is enforced.
Foreign keys are not required to have the same column name as the referenced key, although using similar names often makes database schemas easier to understand. For example, an orders table could technically contain a column named buyer_id that references customers.customer_id. What matters is the relationship declared in the database definition, not whether the two column names match. However, the data types and values generally need to be compatible with the referenced key. Inconsistent types can make constraints difficult or impossible to create. Good schema design therefore uses clear naming conventions and compatible data definitions.
A table can contain more than one foreign key. An orders table, for example, might contain customer_id, salesperson_id, and shipping_address_id, each pointing to a different related table. This allows one record to connect with several parts of the database. A single foreign key may also be referenced by many records in the child table. One customer can therefore appear in hundreds of order rows without duplicating the entire customer record. These connections form the foundation of relational database modeling. Complex applications become manageable because information is separated logically while remaining connected through keys.
Foreign keys can also reference rows within the same table, creating what is known as a self-referencing relationship. An employee table could include manager_id, where each employee’s manager is another employee in the same table. The manager_id foreign key could reference the table’s own employee_id primary key. This approach is useful for hierarchical structures such as organizational charts, category trees, comments with replies, and parent-child menu systems. The concept remains the same even though both sides of the relationship exist in one table. A foreign key always represents a logical connection between records.
Foreign Key vs Primary Key: What Is the Difference?
A primary key and a foreign key are related concepts, but they perform different jobs. A primary key uniquely identifies each row within its own table. A foreign key creates a relationship by referencing a key in another table or another row in the same table. For example, customer_id may be the primary key in a customers table because each customer needs a unique identifier. That same value can appear many times as a foreign key in an orders table because one customer may place many orders. The distinction becomes clearer when you think of the primary key as identity and the foreign key as connection.
Primary key values must be unique within their table. If two customer rows had the same primary key, the database would not be able to reliably distinguish between them. A foreign key, however, does not normally need to be unique because many child rows may reference the same parent row. Twenty orders can therefore contain the same customer ID while remaining separate orders. The uniqueness requirement belongs to the referenced key rather than the foreign key itself. This pattern is what allows one-to-many relationships to work efficiently in relational databases.
Primary keys also generally cannot contain null values because every row needs a valid identity. Foreign keys may allow null values depending on the database definition and business rules. For example, an employee record might have a nullable manager_id because the chief executive may not report to another employee. Similarly, an order might temporarily have no assigned salesperson. If null values are allowed, the database interprets them as the absence of a relationship rather than an invalid reference. Whether foreign keys should be nullable depends on what the application needs.
A primary key can consist of one column or multiple columns. The same is true for foreign keys. A multi-column key is known as a composite key, and a foreign key can reference a composite primary or unique key when the database supports it. For example, a table may uniquely identify records through a combination of country_code and account_number. Another table could use those two columns together as a foreign key. Composite keys can be useful, although many application designs prefer simpler surrogate identifiers for convenience.
The easiest way to remember the distinction is to think about direction. A primary key tells the database, “This value uniquely identifies this record.” A foreign key tells the database, “This record is connected to that other record.” One table’s primary key can therefore become the target of foreign keys in several other tables. These relationships allow databases to avoid duplicating information while still connecting related data. Both types of keys are important, but they solve different problems within relational database design.
Why Do Databases Need Foreign Keys?
Databases need foreign keys primarily to maintain referential integrity. Referential integrity means that relationships between records remain valid as data is inserted, updated, and deleted. Without a foreign key constraint, an orders table might contain a customer ID that does not exist in the customers table. That order would refer to an imaginary customer, creating an orphaned record. A properly configured foreign key can prevent this from happening. The database engine checks the relationship automatically instead of relying entirely on application code to catch every mistake.
Foreign keys also reduce the risk of data inconsistency across applications. Modern databases may be accessed by websites, mobile apps, background jobs, administrative dashboards, reporting tools, and third-party integrations. If relationship validation exists only inside one application, another system could accidentally bypass those rules. A database-level foreign key provides a final layer of protection regardless of which application submits the query. This does not replace application validation, but it strengthens the overall data model. Critical rules are often safest when enforced as close to the data as possible.
Another benefit is clearer database structure. When foreign keys are declared explicitly, developers can understand how tables relate simply by examining the schema. Database modeling tools can often visualize these relationships automatically. This makes complex systems easier to document, maintain, and troubleshoot. Someone joining a project can quickly see that orders.customer_id references customers.customer_id or that comments.post_id references posts.post_id. Without declared relationships, developers may have to infer connections from column names or application code. Explicit foreign keys turn hidden assumptions into documented database rules.
Foreign keys also support safer deletion and update behavior. Suppose a customer has hundreds of associated orders. If someone tries to delete that customer, the database can prevent the deletion, automatically remove related records, or set certain foreign key values to null depending on the configured action. These behaviors help organizations prevent accidental data loss or broken relationships. The appropriate choice varies by context because deleting a blog post and deleting a financial customer record have very different consequences. Foreign key actions give database designers a formal way to define those consequences.
Finally, foreign keys support normalization, which is the process of organizing relational data to reduce unnecessary duplication and undesirable dependencies. Instead of storing department names repeatedly in every employee record, a database can create a departments table and reference it through department_id. This approach makes updates easier and reduces inconsistent spelling or outdated information. Changing a department name can then happen in one place while the relationship remains intact. Foreign keys are not the only component of normalization, but they are central to connecting the normalized tables that result.
How Foreign Keys Work With Simple Examples
Consider a basic customer database. The customers table contains customer_id, name, and email, while the orders table contains order_id, customer_id, order_date, and total_amount. The customer ID in the orders table references the customer ID in the customers table. When someone inserts an order with customer_id = 25, the database checks whether customer 25 exists. If the foreign key is enforced and that customer does not exist, the insert can fail. This prevents an order from becoming disconnected from a valid customer.
The relationship also makes data retrieval more efficient and logical. Instead of copying a customer’s name and email into every order row, a query can join the two tables when that information is needed. An SQL JOIN can match orders.customer_id with customers.customer_id and return combined results. This means the database stores customer information once while still allowing reports to show customer details alongside orders. If an email address changes, the update happens in the customers table. Historical order rows remain connected through the unchanged customer identifier.
A product catalog provides another simple example. A categories table might contain categories such as laptops, monitors, keyboards, and accessories. The products table can include a category_id foreign key indicating which category each product belongs to. Hundreds of products can reference the same category without repeating the full category name in every row. If a category is renamed from “Computer Displays” to “Monitors,” only one category record needs to change. Every related product automatically remains connected to that record through its identifier.
Foreign keys can also represent optional relationships. Imagine an orders table containing a coupon_id column that references a coupons table. Not every customer uses a coupon, so the foreign key might permit null values. An order with no coupon would simply store null in that column, while an order using a promotion would contain a valid coupon ID. If the column contains a non-null value, the database can require that corresponding coupon to exist. This combines flexibility with integrity by allowing absence without permitting invalid references.
More complex systems may use chains of foreign keys across several tables. An ecommerce order could reference a customer, while order items reference the order and each order item references a product. The product may reference a category, manufacturer, or supplier. A single transaction can therefore connect many normalized tables through different key relationships. SQL queries can follow these links when generating reports, displaying order histories, or calculating sales. Foreign keys are what make this interconnected relational structure manageable.
One-to-One, One-to-Many and Many-to-Many Relationships
A one-to-many relationship is the most common type of relationship created with foreign keys. One customer can have many orders, one department can have many employees, and one blog post can have many comments. The foreign key usually appears on the “many” side of the relationship. For example, each order contains one customer ID, but the same customer ID can appear in many order rows. This design keeps the parent table concise while allowing unlimited related child records. Most business databases contain numerous one-to-many relationships of this kind.
A one-to-one relationship means one row in one table corresponds to at most one row in another table. This can be implemented using a foreign key with a unique constraint. For example, a users table might store essential account details while a user_profiles table stores additional optional information. Each profile references one user, and the foreign key is unique so no user can have two profile rows. One-to-one designs can separate sensitive, optional, or infrequently accessed information. They are less common than one-to-many relationships but remain useful in certain schema designs.
A many-to-many relationship occurs when multiple records on each side can be related to multiple records on the other side. Students can enroll in many courses, and each course can contain many students. A single foreign key cannot represent this cleanly. Instead, relational databases typically use a junction table, sometimes called a bridge or associative table. An enrollments table could contain student_id and course_id, with each column serving as a foreign key. Every row then represents one student-course relationship.
Junction tables can also contain information about the relationship itself. In the student example, the enrollments table might include enrollment date, final grade, status, or attendance information. These details belong to the relationship rather than solely to the student or course. Ecommerce databases use a similar pattern when orders contain multiple products and products can appear in many orders. An order_items table connects orders and products through foreign keys. It can also store quantity, price at purchase, discount, and other transaction-specific information.
Understanding relationship types makes foreign key placement much easier. In one-to-many relationships, place the foreign key on the many side. In one-to-one relationships, use a foreign key combined with uniqueness when appropriate. In many-to-many relationships, create a junction table containing foreign keys to both related tables. These patterns are fundamental to relational database design and appear across almost every industry. Once you identify the real-world relationship correctly, the foreign key structure usually follows naturally.
How to Create a Foreign Key in SQL
Creating a foreign key in SQL usually begins by defining the parent table. Suppose you create a customers table with an integer column named customer_id as the primary key. Next, you create an orders table containing its own order_id primary key and a customer_id column. The foreign key constraint on the orders table references customers(customer_id). This tells the database that any non-null customer ID stored in an order must correspond to an existing customer. The exact SQL syntax can vary slightly among MySQL, PostgreSQL, SQL Server, Oracle, and SQLite.
A simplified table definition might conceptually declare FOREIGN KEY (customer_id) REFERENCES customers(customer_id). The constraint can be created directly while creating the table or added later with an ALTER TABLE statement in many database systems. Naming the constraint explicitly can make future maintenance easier. For example, a name such as fk_orders_customer clearly describes what the relationship represents. Good constraint names become especially useful when error messages or migration scripts need to reference them. Consistent naming conventions also improve schema readability.
The referenced and referencing columns should use compatible data types. If the parent primary key is a large integer, the child foreign key should generally use a corresponding integer type rather than storing the value as text. Character-based identifiers should also use compatible lengths and encodings where relevant. Database systems may reject constraint creation when data types are incompatible. Even when conversion is technically allowed, mismatched types can create confusing behavior and performance problems. Designing related columns consistently from the beginning avoids unnecessary migration work later.
Existing data also matters when adding a foreign key to an established table. Suppose the orders table already contains several customer IDs that do not exist in the customers table. The database may refuse to create the constraint because those rows already violate referential integrity. Before adding the foreign key, developers need to identify and correct the orphaned data. They might remove invalid records, create missing parent records, or change incorrect values. Data cleanup is therefore an important part of introducing constraints into legacy databases.
Indexes may also play a role in foreign key performance. The referenced primary or unique key is normally indexed because uniqueness enforcement requires efficient lookup. Indexing the child foreign key column can also improve joins, deletion checks, and queries that retrieve records by parent ID. Some database systems automatically create certain indexes while others do not. Developers should examine actual query patterns rather than adding indexes blindly. Foreign keys enforce relationships, while indexes primarily help the database locate related records efficiently.
ON DELETE and ON UPDATE Foreign Key Actions
Foreign keys can define what should happen when a referenced parent row is deleted. The safest default in many situations is to reject the deletion while related child records still exist. This behavior is commonly associated with RESTRICT or NO ACTION, depending on the database system. Imagine trying to delete a customer who still has historical orders. Blocking that deletion may be desirable because the business needs to preserve transaction history. The application can then require an administrator to archive or deactivate the customer instead. Foreign key restrictions protect against accidental removal of important parent data.
Another option is ON DELETE CASCADE. With cascading deletion, removing a parent record automatically deletes related child records. This can be convenient when child records have no meaningful purpose without the parent. For example, deleting a temporary project might reasonably delete its associated draft notes or intermediate records. However, cascading should be used carefully because one deletion can affect many rows across multiple related tables. In a poorly understood schema, cascades can create unexpectedly large data loss. Database designers should only enable them when automatic child removal accurately represents the business rule.
ON DELETE SET NULL provides another approach when the relationship is optional. Suppose employees can reference a manager through a nullable manager_id. If a manager leaves the organization and their employee row is removed, the system might set the affected employees’ manager IDs to null. The employees remain in the database, but their previous reporting relationship disappears. This action requires the foreign key column to allow null values. It can be useful when the child record should survive independently after the parent relationship ends.
Foreign keys can also specify ON UPDATE behavior when referenced key values change. ON UPDATE CASCADE, for instance, automatically updates matching foreign keys when the referenced key changes. In well-designed databases, primary identifiers often remain stable and therefore change rarely. Surrogate keys such as auto-incrementing integers are generally treated as permanent identifiers. Natural keys, however, may occasionally change if business values are used as keys. Update actions allow designers to determine whether child references should follow those changes automatically.
Choosing the correct referential action requires thinking about data meaning rather than convenience. Orders should probably not disappear simply because someone deletes a customer account, while temporary session data may reasonably disappear with its parent session. Employee records may remain even when a department is removed, perhaps with their department relationship set to null or reassigned first. There is no universal foreign key action suitable for every relationship. The database should reflect the real-world lifecycle of the information it stores.
Common Foreign Key Errors and How to Fix Them
One of the most common foreign key errors occurs when an application tries to insert a child row that references a parent record that does not exist. For example, inserting an order with customer ID 999 will fail if there is no customer 999 and the constraint requires a valid reference. The solution is to verify the parent record before creating the child. Sometimes the error comes from a typo or incorrect ID passed by the application. In other cases, the transaction sequence is wrong and the parent record simply has not been inserted yet. Correcting the data flow usually resolves the issue.
Another common error appears when trying to delete a parent row that still has dependent child records. A database may reject the operation with a foreign key constraint violation. This behavior is often intentional and prevents accidental orphaning. Developers need to decide whether the child records should be deleted, reassigned, preserved, or whether the parent should be archived instead. Changing the constraint to cascade should not be the automatic response to every deletion error. The correct fix depends on the business meaning of the relationship.
Mismatched column definitions can prevent a foreign key from being created. A parent column may use one integer size while the child column uses another incompatible type. Character encodings, unsigned settings, collations, or other database-specific attributes can also matter. Reviewing the schema definitions on both sides is the first troubleshooting step. Developers should confirm that the referenced column is actually a primary or eligible unique key. Once the data definitions match, the constraint can usually be created successfully.
Existing orphan records are another frequent problem in older systems. A company may have operated for years without database-level foreign keys, allowing inconsistent records to accumulate. When developers later attempt to add constraints, the database discovers child records pointing to missing parents. Queries can identify these orphaned rows by using joins or existence checks. Teams can then determine whether the data should be deleted, corrected, or linked to newly created parent records. Adding foreign keys after cleanup helps prevent the same problem from returning.
Migration order can also cause foreign key errors during deployment. Database scripts may attempt to create a child table before the referenced parent table exists, or they may try to delete tables in the wrong sequence. Backup restoration can encounter similar problems when data is loaded without respecting dependencies. Migration tools often provide ways to order changes correctly or temporarily handle constraints during controlled imports. Developers should avoid disabling referential integrity permanently just to make deployment easier. A reliable migration process should ultimately restore and validate all required relationships.
Foreign Key Best Practices for Better Database Design
The first best practice is to create foreign keys for relationships that genuinely matter to data integrity. If an order must belong to an existing customer, enforcing that rule in the database usually provides valuable protection. Relying solely on application code leaves room for mistakes from scripts, imports, administrative tools, or future applications. Database constraints should express fundamental rules that should remain true regardless of how data is accessed. However, constraints should represent real requirements rather than being added mechanically. Good database design begins with understanding the domain.
Consistent naming also improves maintainability. If primary keys use names such as customer_id, related foreign keys should generally use the same descriptive naming unless there is a strong reason not to. Constraint names can follow predictable patterns such as fk_orders_customer. This makes database diagrams, SQL queries, and error messages easier to interpret. Large applications can contain hundreds of foreign keys, so naming discipline becomes increasingly valuable over time. Clear schemas reduce the mental effort required to understand unfamiliar parts of the system.
Choose cascade behavior deliberately. ON DELETE CASCADE is useful when dependent records should always disappear with the parent, but it can be dangerous when valuable historical data is involved. Financial transactions, audit records, medical information, and other regulated or historical data often need preservation rules that make automatic deletion inappropriate. Application developers should review cascading relationships during schema design rather than adding them later as a quick fix for errors. Testing deletion behavior in a safe environment is also important. A single parent record can sometimes indirectly connect to thousands of children.
Index frequently queried foreign key columns when it improves actual workload performance. Joins commonly search child records by parent ID, making these indexes useful in many schemas. They can also help the database check dependent rows when parent records are updated or deleted. However, every index consumes storage and adds overhead to inserts and updates. Indexing strategy should therefore balance read performance against write costs. Query execution plans and production workload data can help determine which indexes provide real value.
Finally, document important relationships and review them as applications evolve. Business rules change, tables are split or merged, and new features introduce new dependencies. A foreign key that made sense several years ago may need to be reconsidered if the data model changes substantially. Schema migrations should preserve integrity while adapting relationships carefully. Automated tests can confirm that invalid references are rejected and expected cascade behavior works correctly. Foreign keys are most effective when treated as part of an actively maintained data model rather than a one-time setup task.
Frequently Asked Questions About Foreign Keys
What is a foreign key in simple terms?
A foreign key is a column that connects one database table to another by referencing a key in the related table. It helps databases keep relationships between records valid and organized.
Can a foreign key contain duplicate values?
Yes. Foreign keys commonly contain duplicate values because multiple child records can reference the same parent record, such as many orders belonging to one customer.
Can a foreign key be null?
Yes, if the database column and relationship are designed to allow null values. A null foreign key generally means that the record currently has no related parent record.
Does every table need a foreign key?
No. A table only needs a foreign key when it has a relationship that should reference another table or another record. Independent lookup or standalone tables may not require one.
What is the main purpose of a foreign key?
The main purpose of a foreign key is to maintain referential integrity between related tables. It prevents invalid references and helps keep relational database data consistent.